The competition to dominate the artificial intelligence landscape is shifting away from the raw power of large language models and toward the specialized data they inhabit. In recent weeks, Google, Dell, and Salesforce have each signaled a strategic pivot toward enterprise AI agents, marking an implicit admission that the next frontier of productivity depends less on the model itself and more on the quality, context, and reliability of the data those models access.
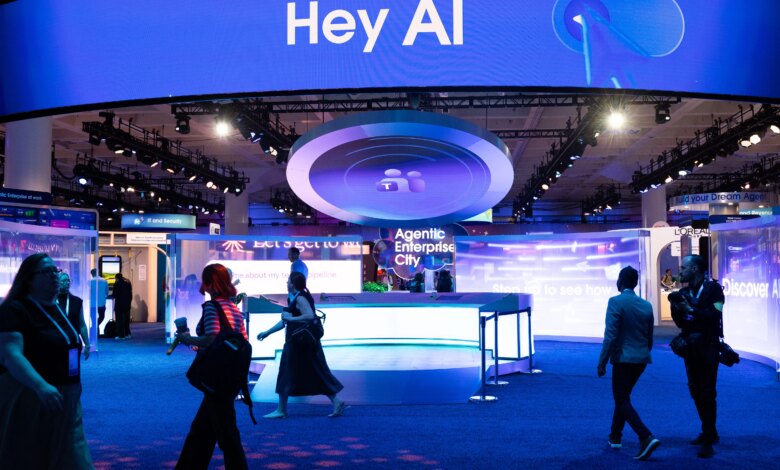
Google has led this push with Gemini for Work, demonstrating how agents can use internal enterprise data to execute complex workflows. Dell recently introduced its own suite of data-centric tools, while Salesforce used its Dreamforce conference to outline an aggressive expansion into agent-driven services. This collective move suggests that the biggest barrier to AI adoption in the corporate world is no longer the intelligence of the software, but the readiness of the information it is expected to analyze.
For nearly a decade, the promise of natural language querying—allowing a user to ask a computer a question in plain English and receive a data-driven answer—remained largely unfulfilled. Early iterations of the technology often failed outside of controlled demonstrations. However, a significant shift occurred in late 2025 as advances in agentic query patterns emerged. These newer models are capable of exploring data, refining their own queries, and checking results for accuracy, making autonomous data analysis practical for the first time.
Despite these technical leaps, industry experts suggest a remaining hurdle: the “context” layer. A model can query a database, but it often lacks the institutional knowledge required to interpret what it finds. For instance, if an AI agent is asked to count a company’s customers, it must understand whether to include free-trial users, how to account for returning customers, or which of several conflicting revenue figures in separate databases is considered the authoritative source by the finance team. These are business-rule definitions rather than technical specifications.
Without this translation layer, enterprise agents risk becoming what some describe as “overconfident interns.” Such tools can produce answers that appear certain but are factually flawed, potentially leading to errors in the boardroom or across various departments. The fear of a CFO receiving a confidently incorrect figure remains a primary reason many organizations have hesitated to grant AI agents a central role in decision-making.
When implemented correctly, however, a robust data layer allows employees to bypass traditional technical bottlenecks. Instead of filing tickets with data teams and waiting for specialists to build reports, managers can query data directly. This shift represents what could be the most significant change in data interaction since the invention of the spreadsheet. For example, a regional sales manager could identify quiet accounts in seconds rather than days, while employees in marketing and support could build their own micro-dashboards to track specific key performance indicators.
This evolution is expected to move beyond simple data visualization and into the realm of custom applications. If an agent can generate a dashboard to identify customers with recurring support issues, it can likely be tasked with building a tool to resolve the problem. This might include identifying accounts that need attention, drafting personalized outreach emails, and presenting them for human review. As organizations move from observing data to acting on it, the competitive advantage will likely belong to those companies that have spent the time making their internal data legible, trustworthy, and ready for automation.